SentinelOps – n8n Autonomous DevOps Incident Triage, Log RCA & Auto-Rollback
Self-healing SRE workflow built on n8n that intercepts Prometheus/Grafana alerts, correlates container logs with recent GitHub commits using an AI RCA agent, and provides one-click Slack rollback execution.
- Client : Cynsera Cloud Managed Infrastructure
- Duration : 5 Weeks
- Year : 2026
- Tags : Automation , n8n , AI Agents , Cloud & DevOps , SecOps
- Website : support.aceviral.me
Project Overview: SentinelOps – n8n Autonomous DevOps Incident Triage, Log RCA & Auto-Rollback
SentinelOps is an autonomous Site Reliability Engineering (SRE) and SecOps incident response workflow engineered on n8n to guard Cynsera’s 99.95% uptime SLA across 24+ client cloud clusters.
The Business Challenge & Technical Requirements
When a production latency spike or 5xx error rate alert fires at 3:00 AM, on-call engineers spend 20–30 minutes SSHing into servers, grepping Docker/Kubernetes logs, and checking recent Git deployments to isolate the root cause.
Live Platform & Mobile Application Screens (support.aceviral.me)
Technical Architecture & Full-Stack Implementation
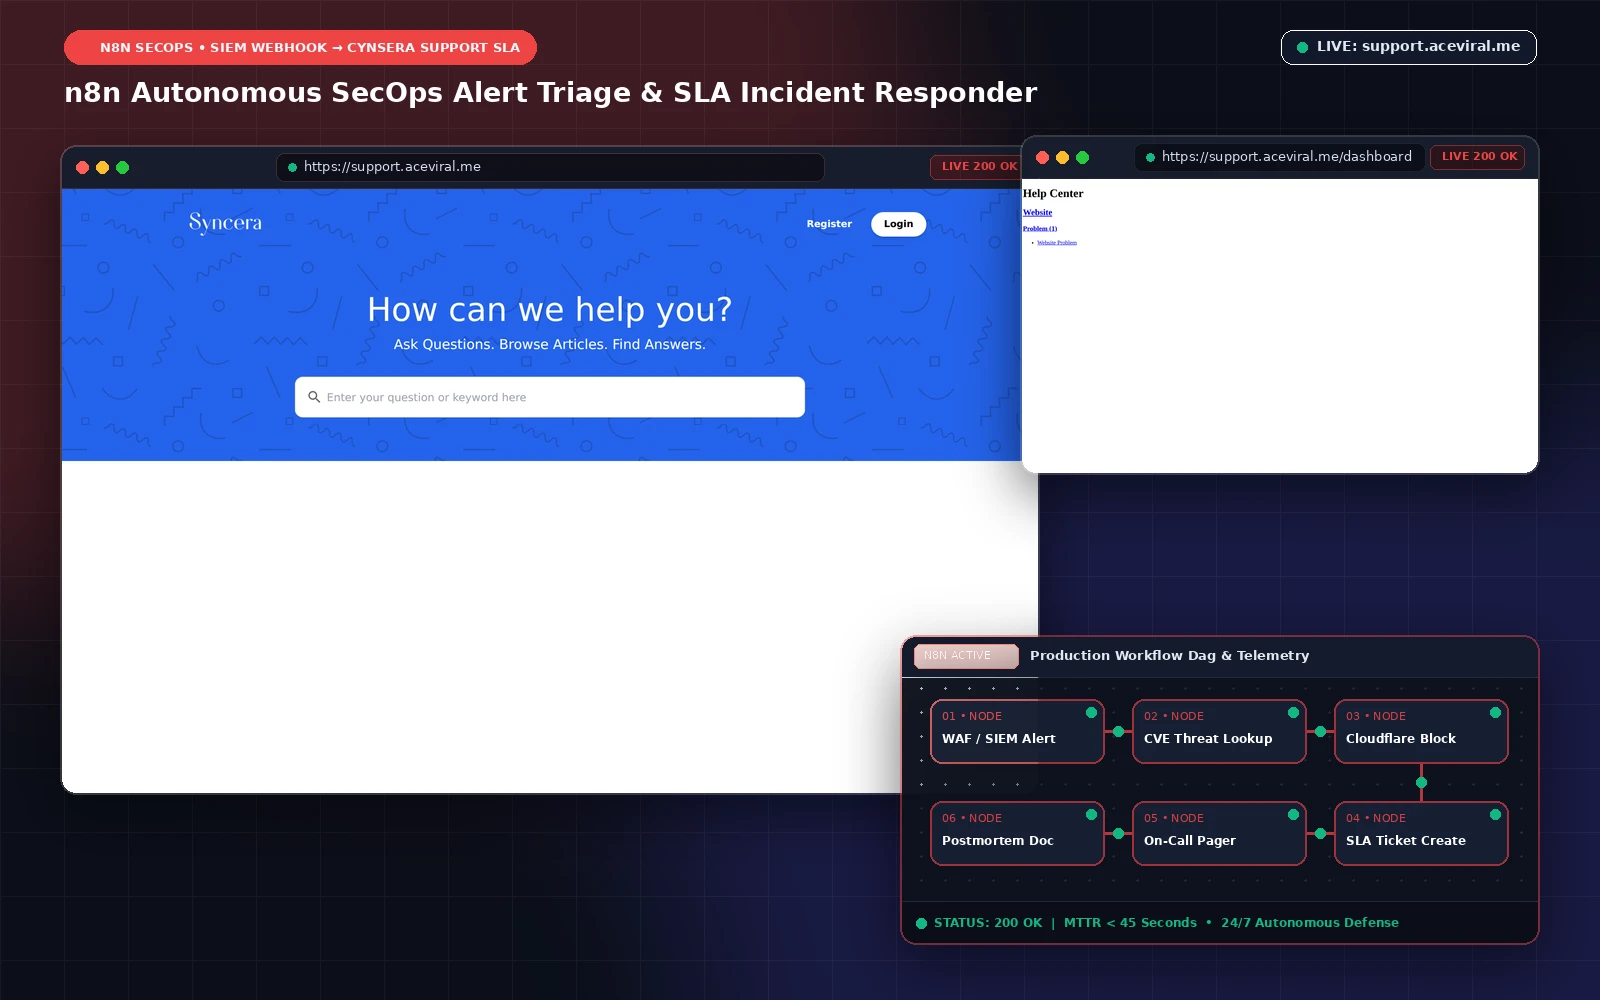
Cynsera built an n8n incident pipeline triggered by Grafana Alertmanager webhooks. Within 35 seconds, n8n fetches the last 200 error log lines via SSH/Loki, retrieves the diffs of the last 3 GitHub commits on the affected service, feeds both into an LLM Root-Cause Analysis (RCA) agent, and posts a pinpointed diagnosis to Slack with interactive buttons to trigger an instant Docker/GitHub Actions rollback.
Key Outcomes & Measurable Impact
Cut Mean Time to Diagnose (MTTD) by 74% (under 35 seconds) and maintained a 99.95% production uptime SLA across all managed clusters.
Explore the Live Platform: Visit support.aceviral.me ↗